
Binary Tree Postorder Traversal
EasyPrompt
Given the root of a binary tree, return the postorder traversal of its nodes' values.
Example 1:
Input: root = [1,null,2,3]
Output: [3,2,1]
Explanation:
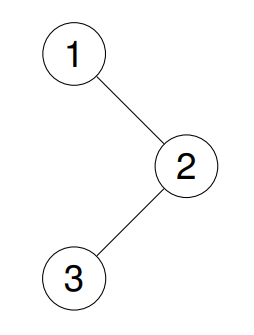
Example 2:
Input: root = [1,2,3,4,5,null,8,null,null,6,7,9]
Output: [4,6,7,5,2,9,8,3,1]
Explanation:
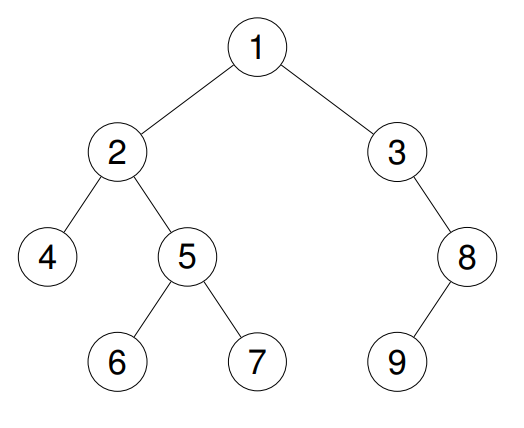
Example 3:
Input: root = []
Output: []
Example 4:
Input: root = [1]
Output: [1]
Constraints:
- The number of the nodes in the tree is in the range
[0, 100]. -100 <= Node.val <= 100
Follow up: Recursive solution is trivial, could you do it iteratively?
Approaches
4 approaches with complexity analysis and trade-offs.
The most intuitive approach to postorder traversal is using recursion. This method directly follows the definition of postorder traversal: traverse the left subtree, then the right subtree, and finally visit the root node. A helper function is typically used to manage the recursive calls.
Algorithm
- Define a helper function, say
traverse(node, resultList). - The base case for the recursion is if the
nodeisnull, in which case we simply return. - If the node is not null, recursively call the
traversefunction for the left child:traverse(node.left, resultList). - After the left subtree has been fully explored, recursively call the
traversefunction for the right child:traverse(node.right, resultList). - Finally, after both left and right subtrees have been traversed, add the value of the current node to the
resultList:resultList.add(node.val). - The main function initializes an empty list and calls the helper function with the root of the tree.
Walkthrough
This approach leverages the call stack to keep track of the nodes. When a function is called for a node, it first makes a recursive call for its left child. This process continues until a null node is reached. Then, the execution unwinds, and a recursive call is made for the right child. Only after both the left and right recursive calls for a node have returned, is the node's value added to the result list. This naturally ensures the 'Left -> Right -> Root' order.
/** * Definition for a binary tree node. * public class TreeNode { * int val; * TreeNode left; * TreeNode right; * TreeNode() {} * TreeNode(int val) { this.val = val; } * TreeNode(int val, TreeNode left, TreeNode right) { * this.val = val; * this.left = left; * this.right = right; * } * } */class Solution { public List<Integer> postorderTraversal(TreeNode root) { List<Integer> result = new ArrayList<>(); traverse(root, result); return result; } private void traverse(TreeNode node, List<Integer> result) { if (node == null) { return; } // 1. Traverse left subtree traverse(node.left, result); // 2. Traverse right subtree traverse(node.right, result); // 3. Visit the root result.add(node.val); }}Complexity
Time
O(N)
Space
O(H)
Trade-offs
Pros
The code is simple, clean, and easy to understand as it directly maps to the definition of postorder traversal.
Cons
For a very deep or skewed tree, the recursion depth can become very large, potentially leading to a
StackOverflowError.
An iterative solution can be devised using two stacks. This approach is a clever modification of an iterative preorder traversal. The idea is to perform a traversal in the order of Root -> Right -> Left and then reverse the result to get the postorder traversal Left -> Right -> Root.
Algorithm
- If the
rootis null, return an empty list. - Create two stacks,
stack1andstack2. - Push the
rootnode ontostack1. - Loop as long as
stack1is not empty: a. Pop a node fromstack1. b. Push this popped node ontostack2. c. If the node's left child exists, push it ontostack1. d. If the node's right child exists, push it ontostack1. - The order of pushing left then right children onto
stack1results instack2storing nodes in the order: Root, Right, Left. - Create a result list.
- Pop all nodes from
stack2and add their values to the result list. This reverses theRoot -> Right -> Leftorder toLeft -> Right -> Root. - Return the result list.
Walkthrough
We use a first stack (stack1) to perform a custom traversal. We start by pushing the root. In a loop, we pop a node, push it to a second stack (stack2), and then push its left and right children (if they exist) onto stack1. By pushing the left child before the right child, the right child will be processed first, leading to a Root -> Right -> Left processing order. The stack2 will store the nodes in this sequence. Finally, we pop all elements from stack2 into our result list, which effectively reverses the sequence to the desired postorder traversal.
class Solution { public List<Integer> postorderTraversal(TreeNode root) { LinkedList<Integer> result = new LinkedList<>(); if (root == null) { return result; } Stack<TreeNode> stack = new Stack<>(); stack.push(root); while (!stack.isEmpty()) { TreeNode node = stack.pop(); // Add to the front of the list, which is equivalent to reversing result.addFirst(node.val); // Push left child first, so right child is processed first if (node.left != null) { stack.push(node.left); } if (node.right != null) { stack.push(node.right); } } return result; }}// Note: The above code is an optimization of the two-stack approach.// It uses one stack and a LinkedList, adding elements to the front// which achieves the reversal without a second stack explicitly.// A literal two-stack implementation would be:/*Stack<TreeNode> s1 = new Stack<>();Stack<TreeNode> s2 = new Stack<>();s1.push(root);while(!s1.isEmpty()){ TreeNode node = s1.pop(); s2.push(node); if(node.left != null) s1.push(node.left); if(node.right != null) s1.push(node.right);}List<Integer> result = new ArrayList<>();while(!s2.isEmpty()){ result.add(s2.pop().val);}return result;*/Complexity
Time
O(N)
Space
O(N)
Trade-offs
Pros
Avoids recursion, thus preventing
StackOverflowErroron deep trees.Conceptually simpler than the one-stack iterative solution.
Cons
Requires O(N) extra space for the stacks, which is less space-efficient than the one-stack iterative or Morris traversal approaches.
A more space-efficient iterative solution uses only one stack. This method simulates the recursion more closely by manually managing the traversal state. It requires tracking not only the nodes in the current path but also the last node that was visited to decide when to process a node.
Algorithm
- Initialize an empty
resultlist, an emptystack, and setcurrenttoroot. - Use a
lastVisitednode pointer, initialized tonull. - Loop while
currentis notnullor thestackis not empty. - Inside the loop:
a. While
currentis notnull, push it onto thestackand move to its left child (current = current.left). b. Whencurrentbecomesnull, peek at the node on top of the stack (peekNode). c. Check ifpeekNodehas a right child and if that right child has not been visited yet (peekNode.right != null && peekNode.right != lastVisited). d. If it does, it means we need to traverse the right subtree. Setcurrent = peekNode.rightand continue the loop. e. Otherwise (no right child, or right child already visited), it's time to visitpeekNode. Pop it from the stack, add its value toresult, and updatelastVisited = peekNode.
Walkthrough
The algorithm traverses down the leftmost path of the tree, pushing each node onto a stack. When it can't go left anymore, it peeks at the stack's top node. It then checks if this node has a right subtree that hasn't been visited yet. If so, it switches to traversing that right subtree. If not (either no right child or the right child has already been visited and processed), it means both children have been dealt with, so it's time to 'visit' the node itself. The node is popped, its value is added to the result, and it's marked as the lastVisited node. This lastVisited check is crucial to prevent getting into an infinite loop by repeatedly trying to visit the same right subtree.
class Solution { public List<Integer> postorderTraversal(TreeNode root) { List<Integer> result = new ArrayList<>(); if (root == null) { return result; } Stack<TreeNode> stack = new Stack<>(); TreeNode current = root; TreeNode lastVisited = null; while (current != null || !stack.isEmpty()) { while (current != null) { stack.push(current); current = current.left; } TreeNode peekNode = stack.peek(); // If right child exists and hasn't been visited yet if (peekNode.right != null && peekNode.right != lastVisited) { current = peekNode.right; } else { // Visit the node stack.pop(); result.add(peekNode.val); lastVisited = peekNode; } } return result; }}Complexity
Time
O(N)
Space
O(H)
Trade-offs
Pros
More space-efficient than the two-stack method, with space complexity proportional to the tree's height.
Avoids recursion limits.
Cons
The logic is more complex and harder to reason about compared to the recursive and two-stack approaches.
Morris Traversal is an advanced technique that achieves a tree traversal with O(1) auxiliary space, excluding the result list. It works by temporarily modifying the tree's pointers to create 'threads' that guide the traversal, eliminating the need for a stack or recursion. For postorder, a common strategy is to perform a Morris traversal that yields a reversed-preorder (Root -> Right -> Left) and then reverse the final list.
Algorithm
- Create an empty list
result. - Set
currenttoroot. - While
currentis not null: a. Ifcurrent.rightis null, it means there's no right subtree to visit before the left. Addcurrent.valto theresultand move left (current = current.left). b. Ifcurrent.rightis not null, find the inorder predecessor ofcurrentin its right subtree. This is the leftmost node of the right subtree (predecessor). c. Ifpredecessor.leftis null (no thread exists), addcurrent.valtoresult, create a thread frompredecessorback tocurrent(predecessor.left = current), and move right (current = current.right). d. Ifpredecessor.leftpoints tocurrent(thread exists), it means we have finished the traversal ofcurrent's right subtree. Remove the thread (predecessor.left = null) and move left (current = current.left). - After the loop, the
resultlist contains the nodes inRoot -> Right -> Leftorder. - Reverse the
resultlist to get the final postorder traversal. - Return the reversed list.
Walkthrough
The core idea is to adapt the Morris traversal logic. Instead of linking the inorder predecessor to the current node for an inorder traversal, we adapt it for a Root -> Right -> Left traversal. We traverse the tree, and for each node, we check its right child. If no right child exists, we process the node and move to the left child. If a right child exists, we find its inorder predecessor (the leftmost node in the right subtree). We then create a temporary link (thread) from this predecessor back to the current node. This thread allows us to return to the current node after visiting its right subtree. By carefully adding nodes to our result list before traversing the right subtree and then reversing the entire list at the end, we achieve the postorder sequence. This method cleverly uses the tree's own null pointers to store the path, thus achieving O(1) space complexity.
class Solution { public List<Integer> postorderTraversal(TreeNode root) { LinkedList<Integer> result = new LinkedList<>(); TreeNode current = root; while (current != null) { if (current.right == null) { result.addFirst(current.val); current = current.left; } else { TreeNode predecessor = current.right; while (predecessor.left != null && predecessor.left != current) { predecessor = predecessor.left; } if (predecessor.left == null) { result.addFirst(current.val); predecessor.left = current; // Create thread current = current.right; } else { predecessor.left = null; // Remove thread current = current.left; } } } return result; }}Complexity
Time
O(N)
Space
O(1)
Trade-offs
Pros
Extremely space-efficient, using O(1) auxiliary space.
Completely iterative and does not risk stack overflow.
Cons
The algorithm is highly complex and non-intuitive.
It temporarily modifies the tree structure, which can be problematic in a multi-threaded environment if not handled carefully.
Solutions
Solution
/** * Definition for a binary tree node. * public class TreeNode { * int val; * TreeNode left; * TreeNode right; * TreeNode() {} * TreeNode(int val) { this.val = val; } * TreeNode(int val, TreeNode left, TreeNode right) { * this.val = val; * this.left = left; * this.right = right; * } * } */ class Solution { public List < Integer > postorderTraversal ( TreeNode root ) { LinkedList < Integer > ans = new LinkedList <>(); while ( root != null ) { if ( root . right == null ) { ans . addFirst ( root . val ); root = root . left ; } else { TreeNode next = root . right ; while ( next . left != null && next . left != root ) { next = next . left ; } if ( next . left == null ) { ans . addFirst ( root . val ); next . left = root ; root = root . right ; } else { next . left = null ; root = root . left ; } } } return ans ; } }/** * Definition for a binary tree node. * struct TreeNode { * int val; * TreeNode *left; * TreeNode *right; * TreeNode() : val(0), left(nullptr), right(nullptr) {} * TreeNode(int x) : val(x), left(nullptr), right(nullptr) {} * TreeNode(int x, TreeNode *left, TreeNode *right) : val(x), left(left), right(right) {} * }; */ class Solution { public: vector < int > postorderTraversal ( TreeNode * root ) { vector < int > ans ; while ( root ) { if ( ! root -> right ) { ans . push_back ( root -> val ); root = root -> left ; } else { TreeNode * next = root -> right ; while ( next -> left && next -> left != root ) { next = next -> left ; } if ( ! next -> left ) { ans . push_back ( root -> val ); next -> left = root ; root = root -> right ; } else { next -> left = nullptr ; root = root -> left ; } } } reverse ( ans . begin (), ans . end ()); return ans ; } };# Definition for a binary tree node. # class TreeNode: # def __init__(self, val=0, left=None, right=None): # self.val = val # self.left = left # self.right = right class Solution : def postorderTraversal ( self , root : Optional [ TreeNode ]) -> List [ int ]: ans = [] while root : if root . right is None : ans . append ( root . val ) root = root . left else : next = root . right while next . left and next . left != root : next = next . left if next . left != root : ans . append ( root . val ) next . left = root root = root . right else : next . left = None root = root . left return ans [:: - 1 ]Video walkthrough
Newsletter
One sharp idea, every week
System design and interview prep — short enough to finish.
No spam. Unsubscribe anytime.
Practice
Same difficulty — related problems to reinforce the pattern.